We turn data into production-grade AI, not just demos.
WIEWAVE designs data platforms, builds machine learning pipelines and ships applied AI — including LLM-powered features — with the MLOps, security and governance discipline production systems demand. From ingestion to inference, every system we deliver is built to run continuously for clients worldwide, on Azure, AWS or Google Cloud.
AI and data systems, engineered end to end
From the data platform underneath to the AI product on top — data engineering, machine learning, applied AI, analytics, IoT, workflow automation and the governance to run it responsibly.
Data Engineering & Platforms
We design and build the data platforms AI depends on — ingestion pipelines, warehouses and lakehouses, and data models engineered for reliability, governance and scale.
Machine Learning & MLOps
Model training pipelines, experiment tracking, versioning and CI/CD for ML — the operational discipline that takes a model from notebook to production service.
Applied AI & LLM Integrations
We integrate large language models and applied AI into real products — retrieval-augmented generation, workflow copilots and API-driven AI features built on your own data.
Data Analytics & BI
Dashboards, reporting pipelines and business intelligence that turn raw operational data into decisions your teams can act on.
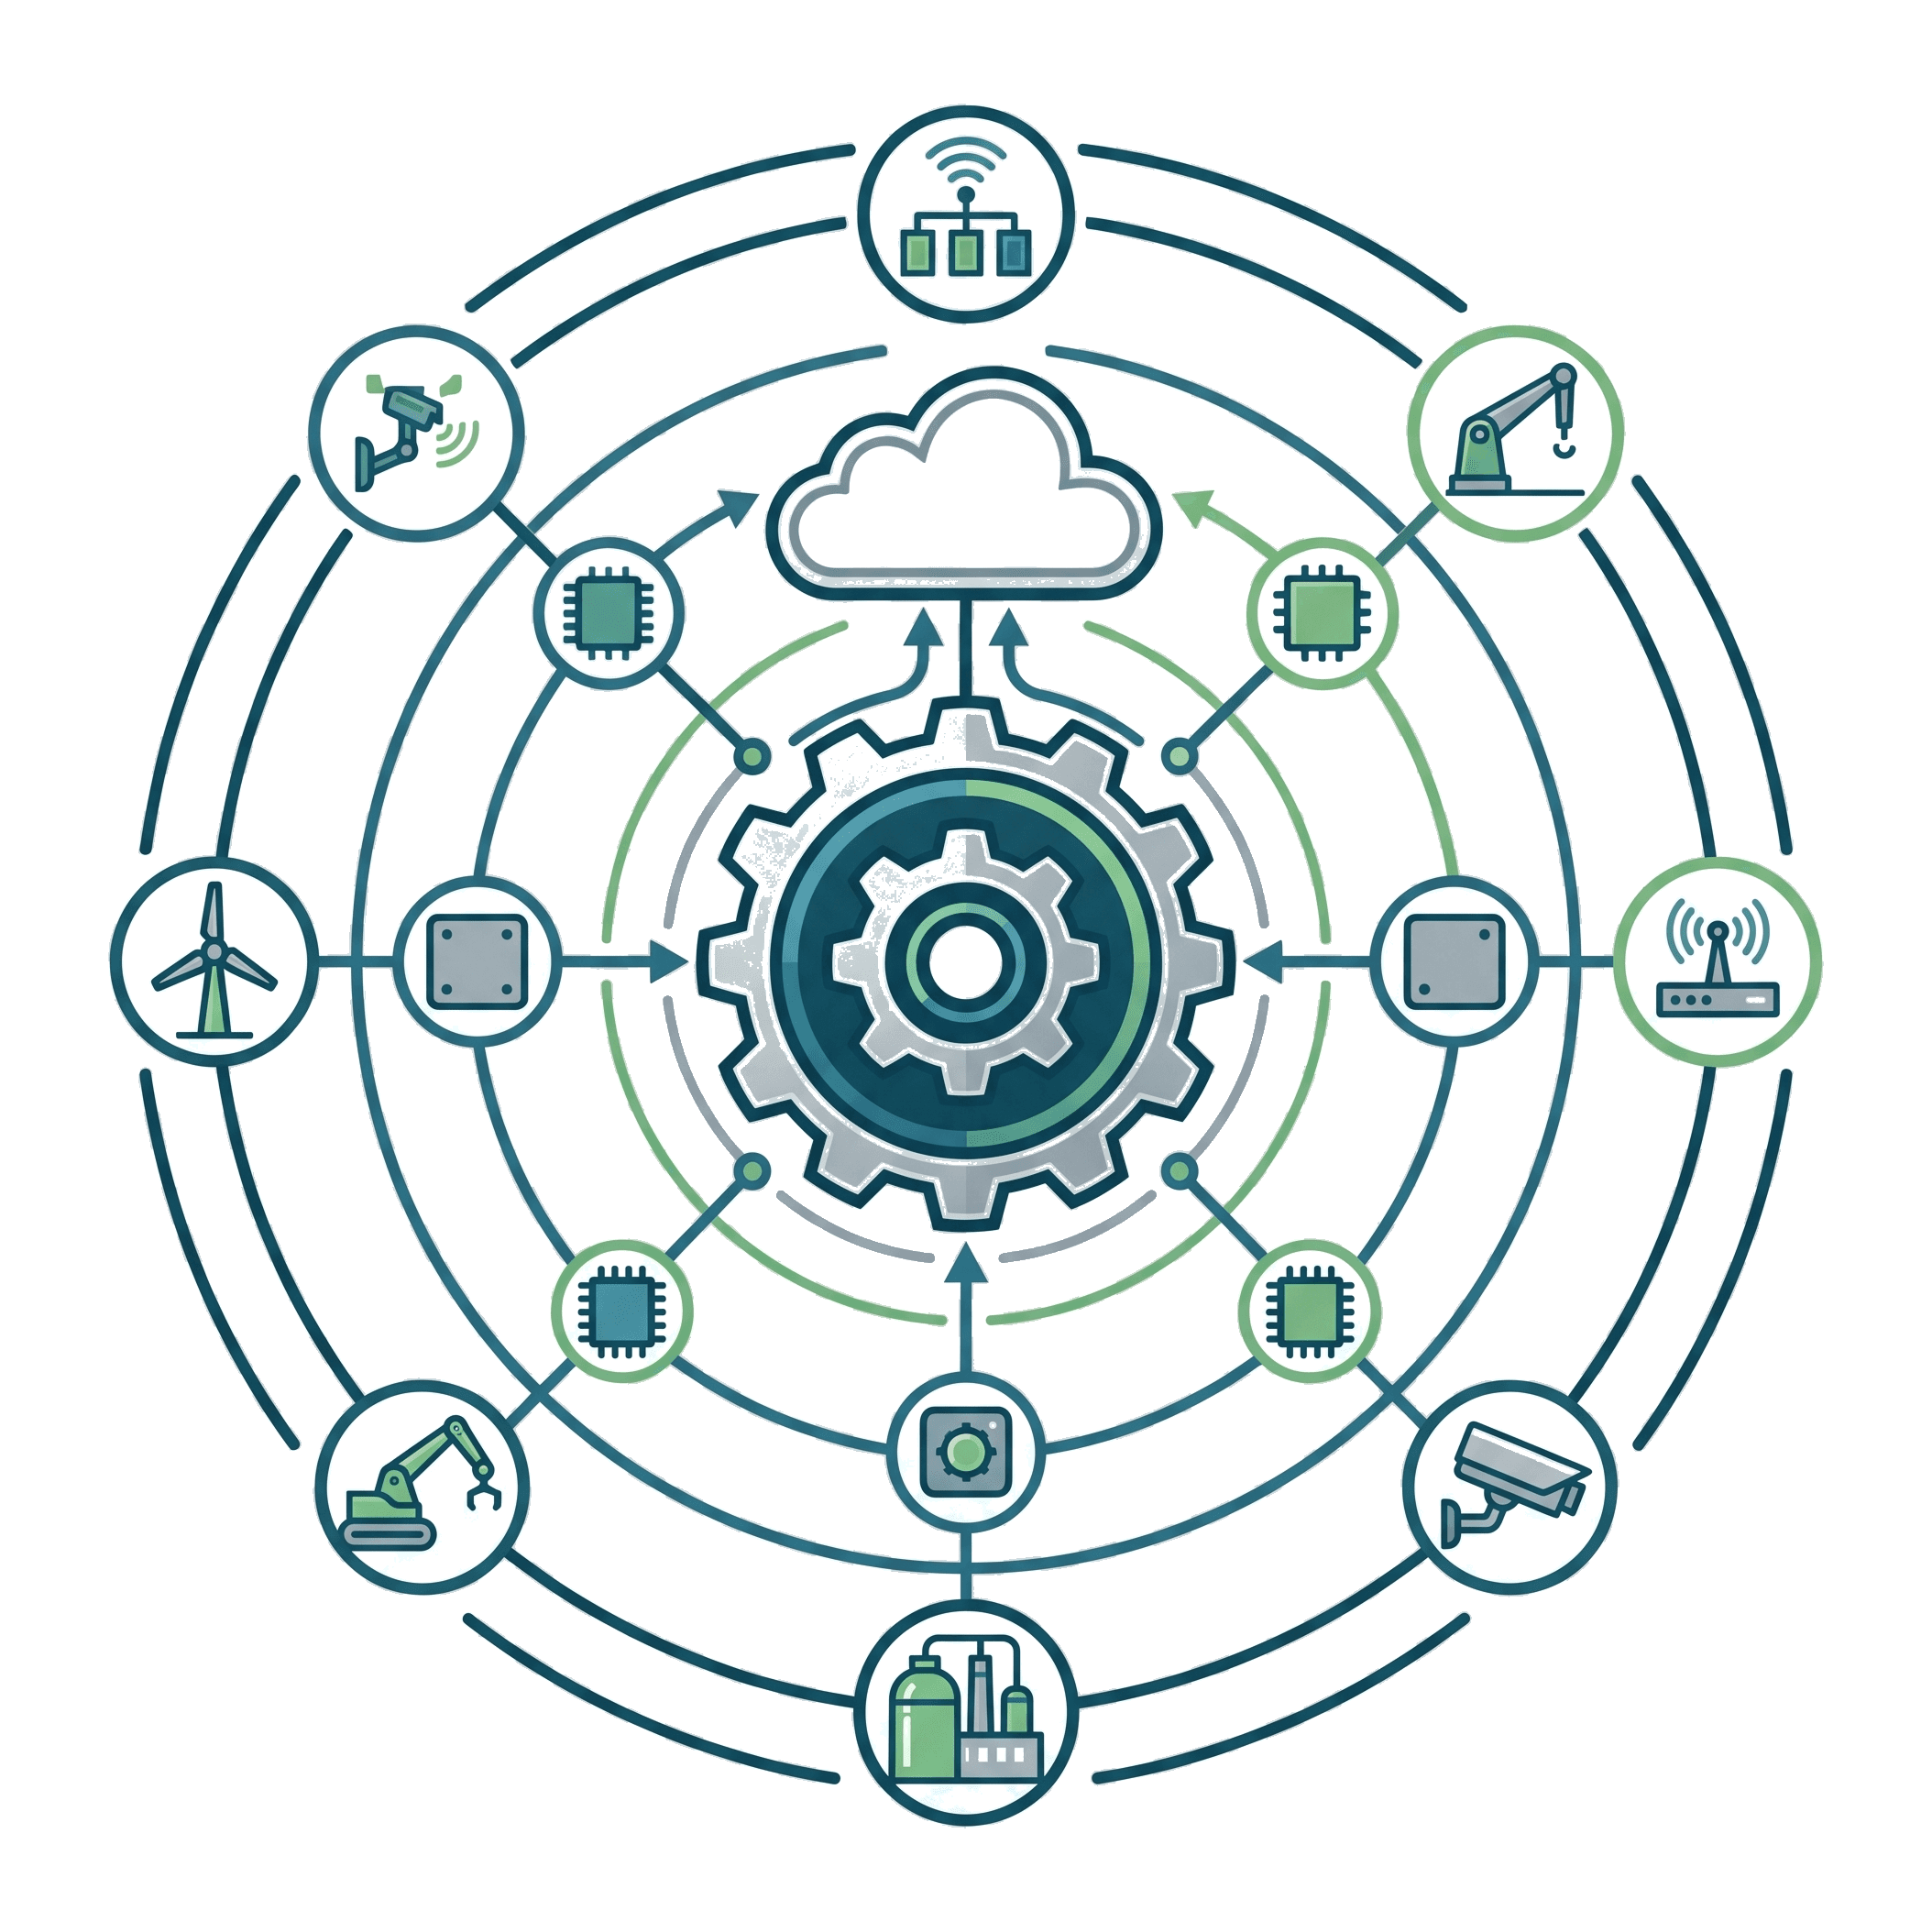
IoT & Edge Data Pipelines
Device and sensor data pipelines from edge to cloud — ingestion, streaming and storage architectures built for connected devices and industrial IoT.
Responsible AI, Security & Governance
Access controls, data governance and monitoring built into every AI system we ship — plus workflow automation (RPA) and blockchain-backed data integrity where the use case calls for it.
The data & AI stack we build on
From data to production, in four stages
The same pipeline underlies every AI or analytics system we ship — repeatable, monitored and built to keep working after launch.
 Step 01
Ingest & Store
Data from applications, devices and third-party systems lands in a governed lake or warehouse, versioned and ready to use.
 Step 02
Model & Experiment
Engineers explore, feature-engineer and train models with tracked experiments — reproducible, not ad hoc.
 Step 03
Deploy & Serve
Models and AI services ship behind versioned APIs, with CI/CD, containers and infrastructure-as-code doing the heavy lifting.
 Step 04
Monitor & Retrain
Live systems are watched for drift and performance, with retraining pipelines that keep models accurate over time.
AI, ML & data questions, answered
What teams usually ask before we build a data platform, an ML pipeline or an AI feature. New to the topic? Read MLOps explained.
Have a data or AI system to build?
Tell us about your data, your use case and where it needs to run — we'll get back to you within one business day.